Latest articles, tutorials, and updates from EnConvert
An agent reads a technical manual and answers the installation question instantly, confidently, and wrongly. The team spends two days tuning prompts and trying ...
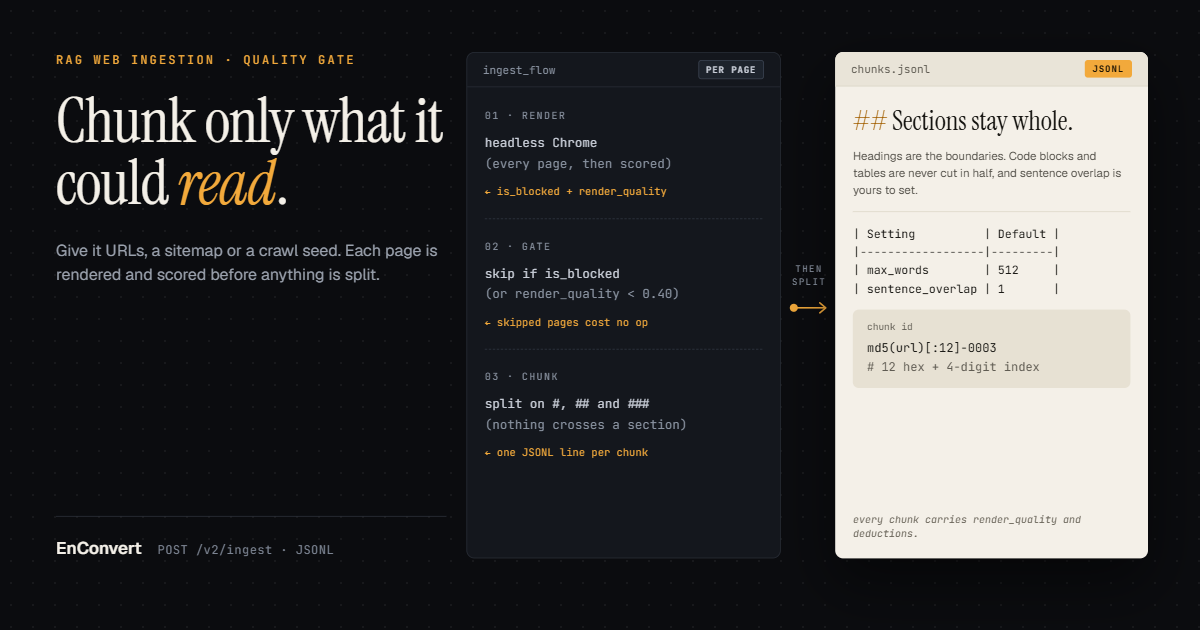
How EnConvert's RAG web ingestion API crawls a site, renders each page in Chrome, skips pages it couldn't read, and writes heading-aware JSONL chunks.
Search, map, read, extract, ingest, watch and open files from one agent web data API. Which verbs are GA, which are private beta, and the gotchas.
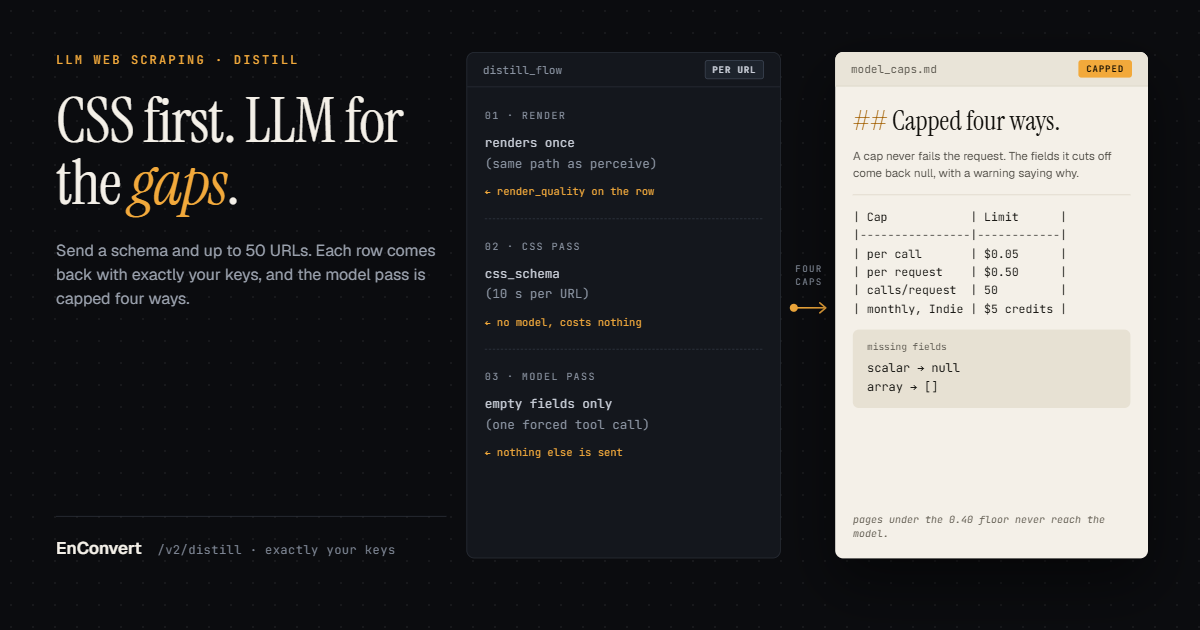
22 of 33 QA tests on /v2/perceive sent a key it didn't know and got a 200. What our LLM web scraping API does with guessed keys and invented fields.
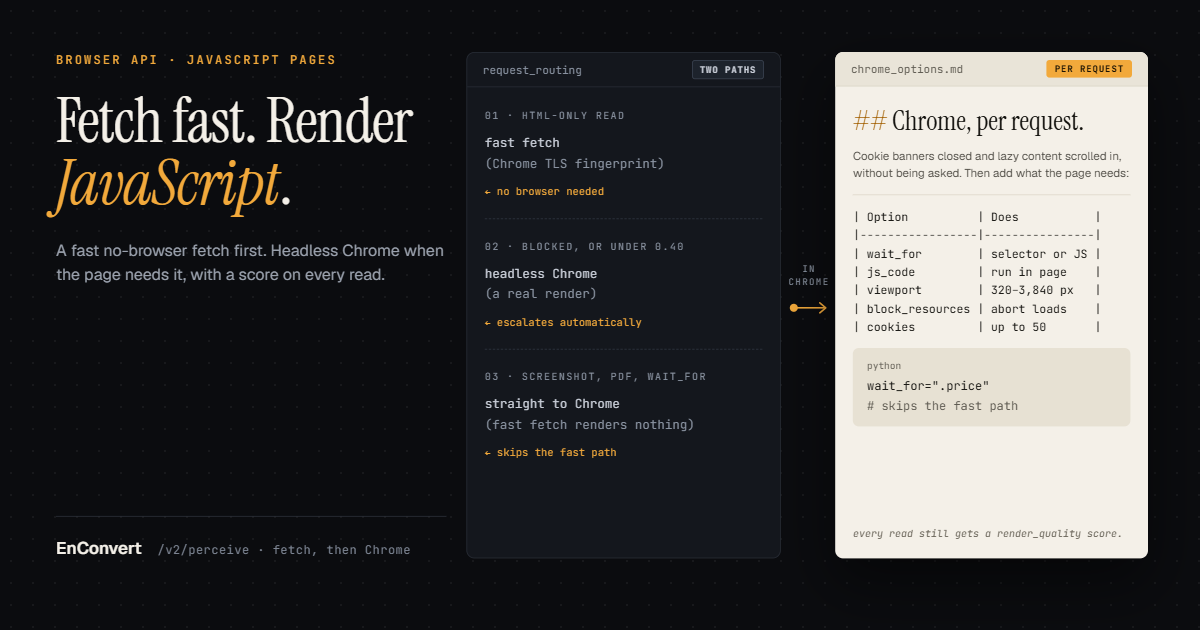
What our AI agent web browser API does with pages that need JavaScript (wait, run JS, screenshot, PDF), and where it stops: no click-through flows yet.
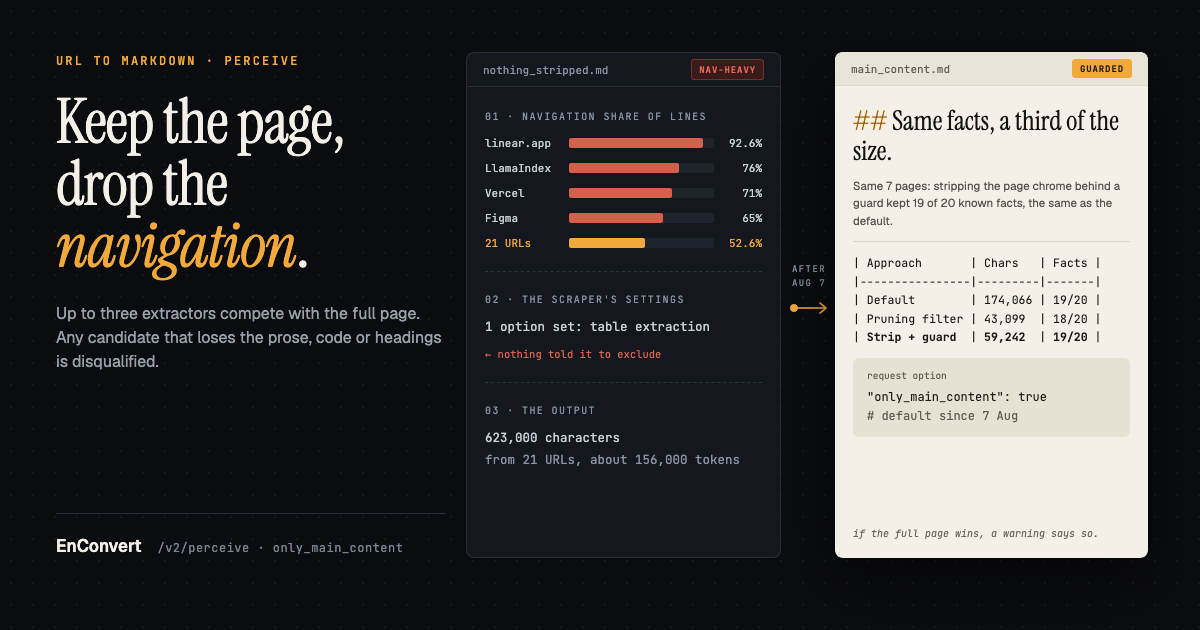
52.6% of our markdown lines were navigation. A stricter filter emptied 5 of 7 pages. How EnConvert's URL to Markdown API picks main content now.
Firecrawl called Alexandria a knowledge library. The docs tell a different story. A closer look at what the product actually is, why the move makes sense, and w...
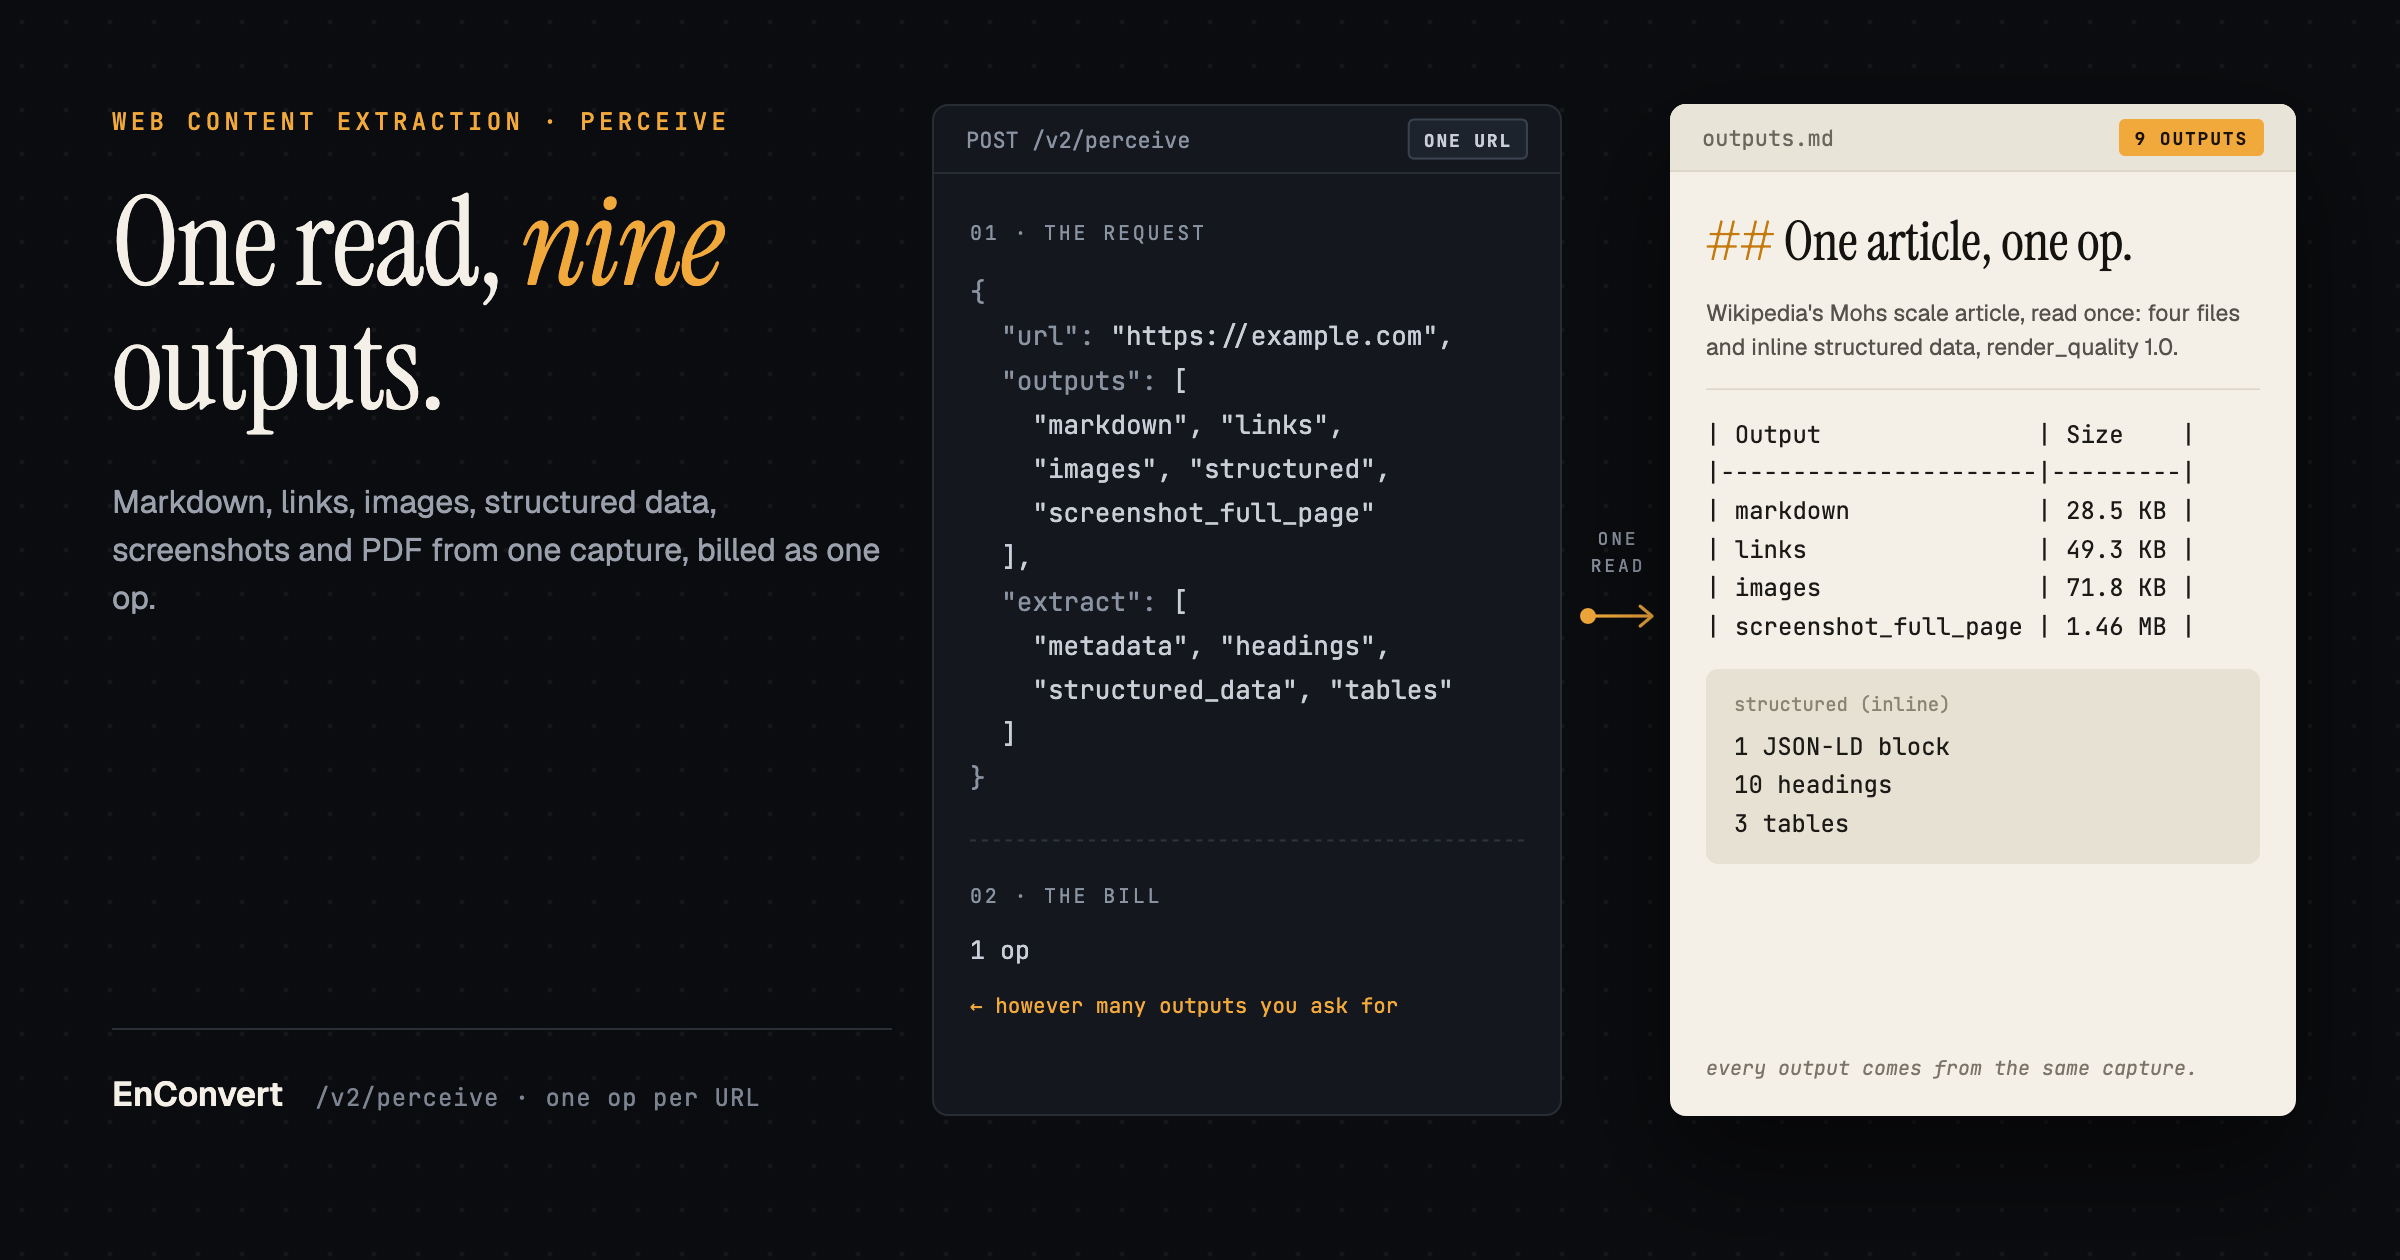
Markdown, links, images, structured data, screenshots and PDFs from one URL read and one op: what each output contains and when to use which.
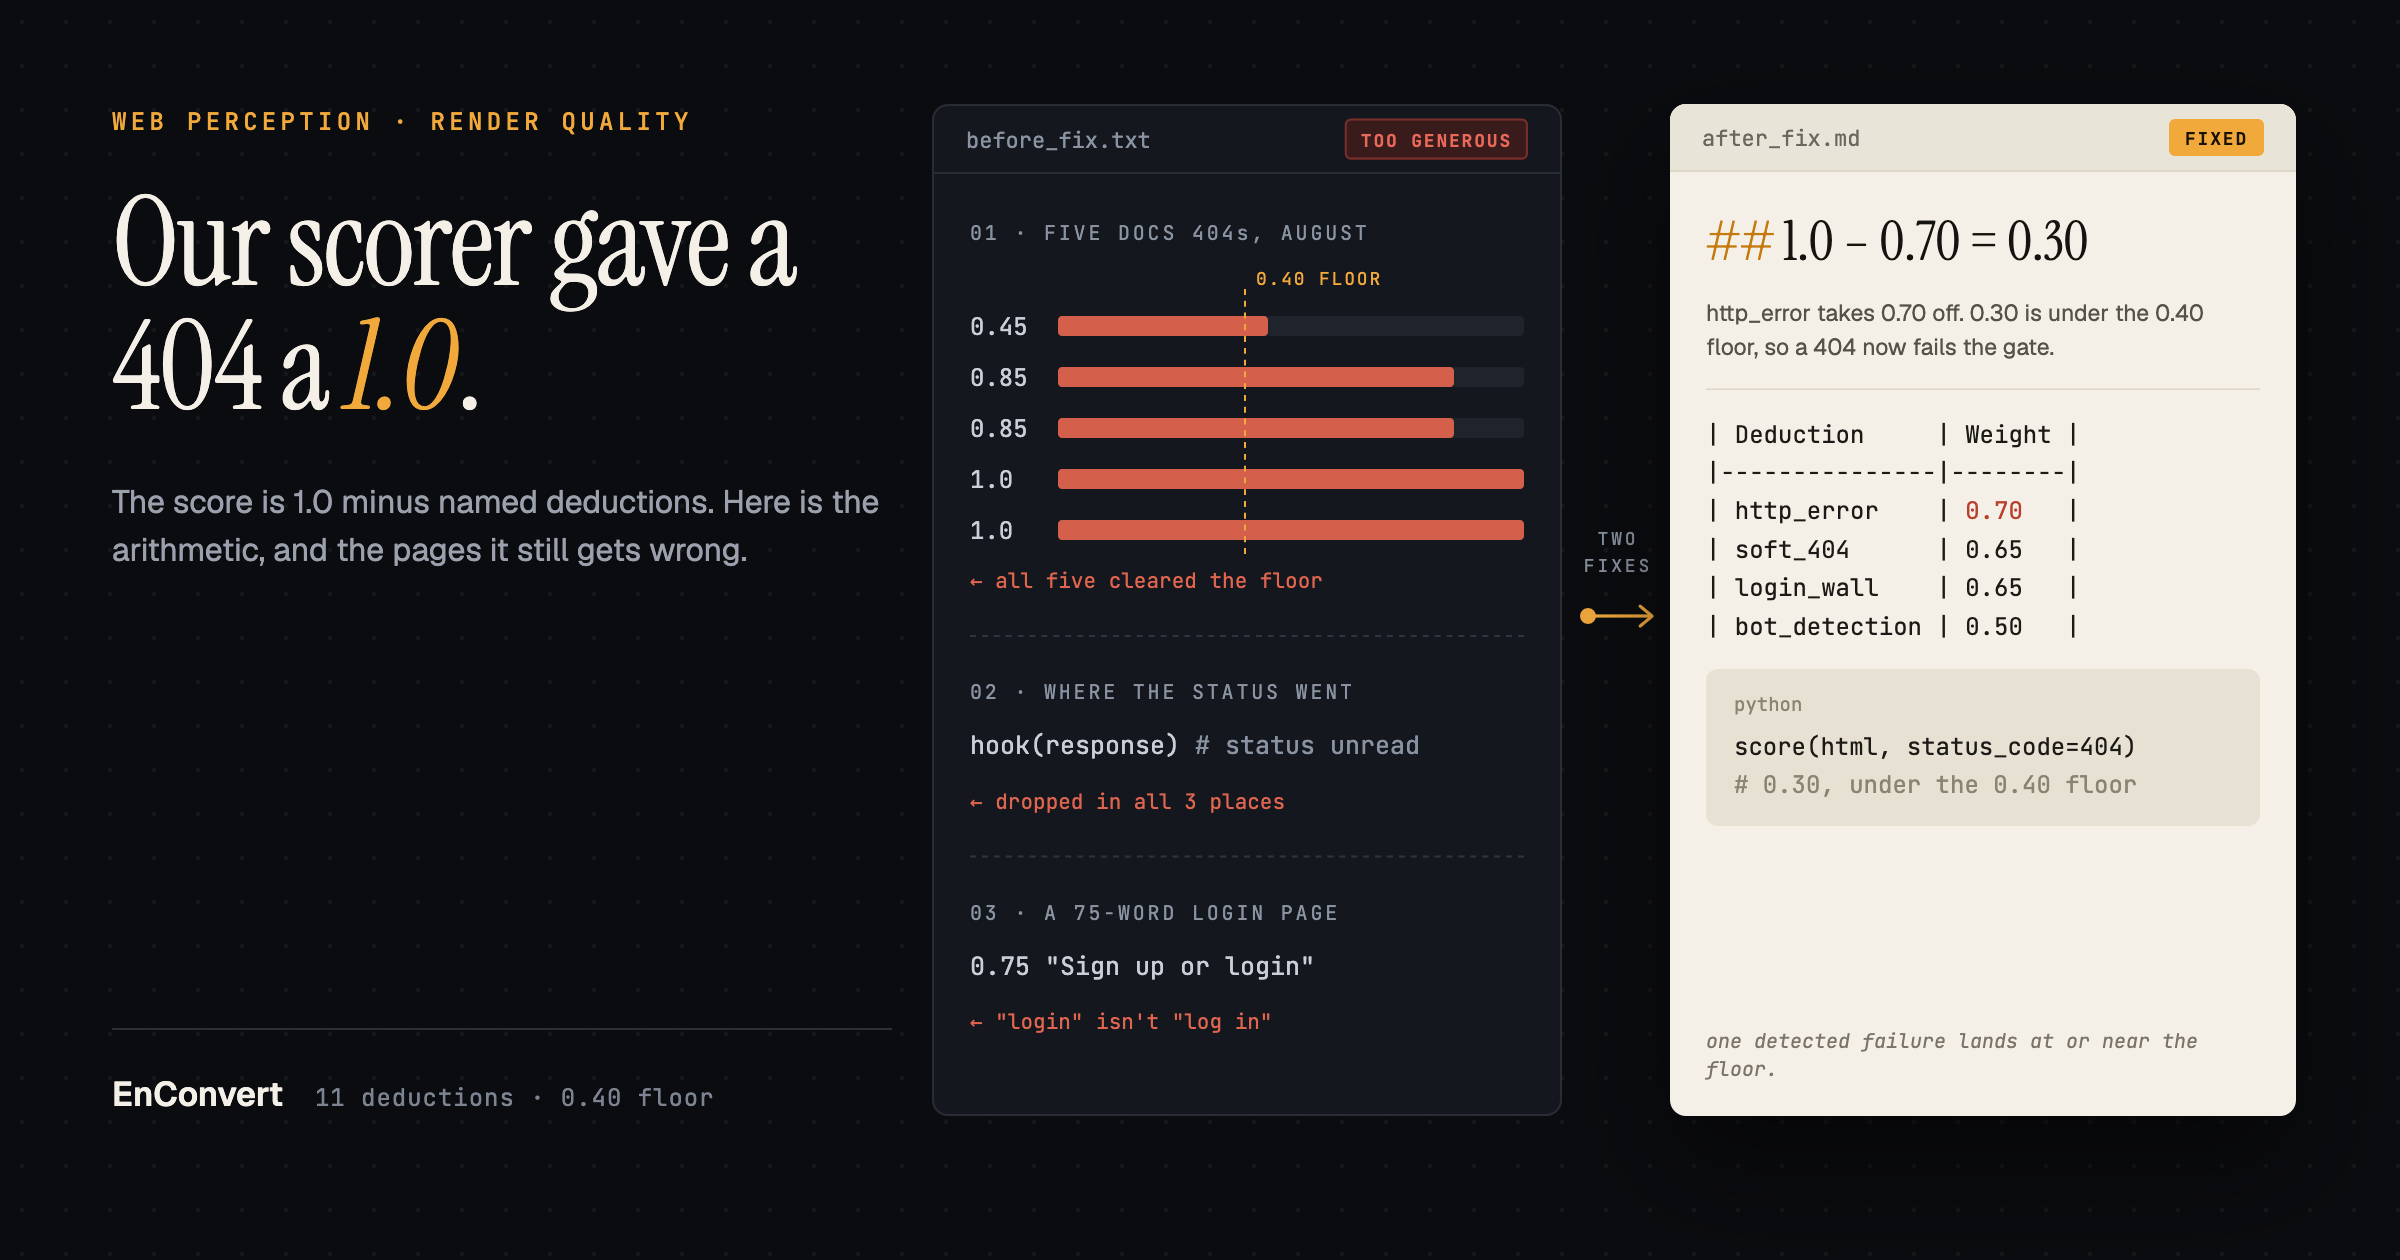
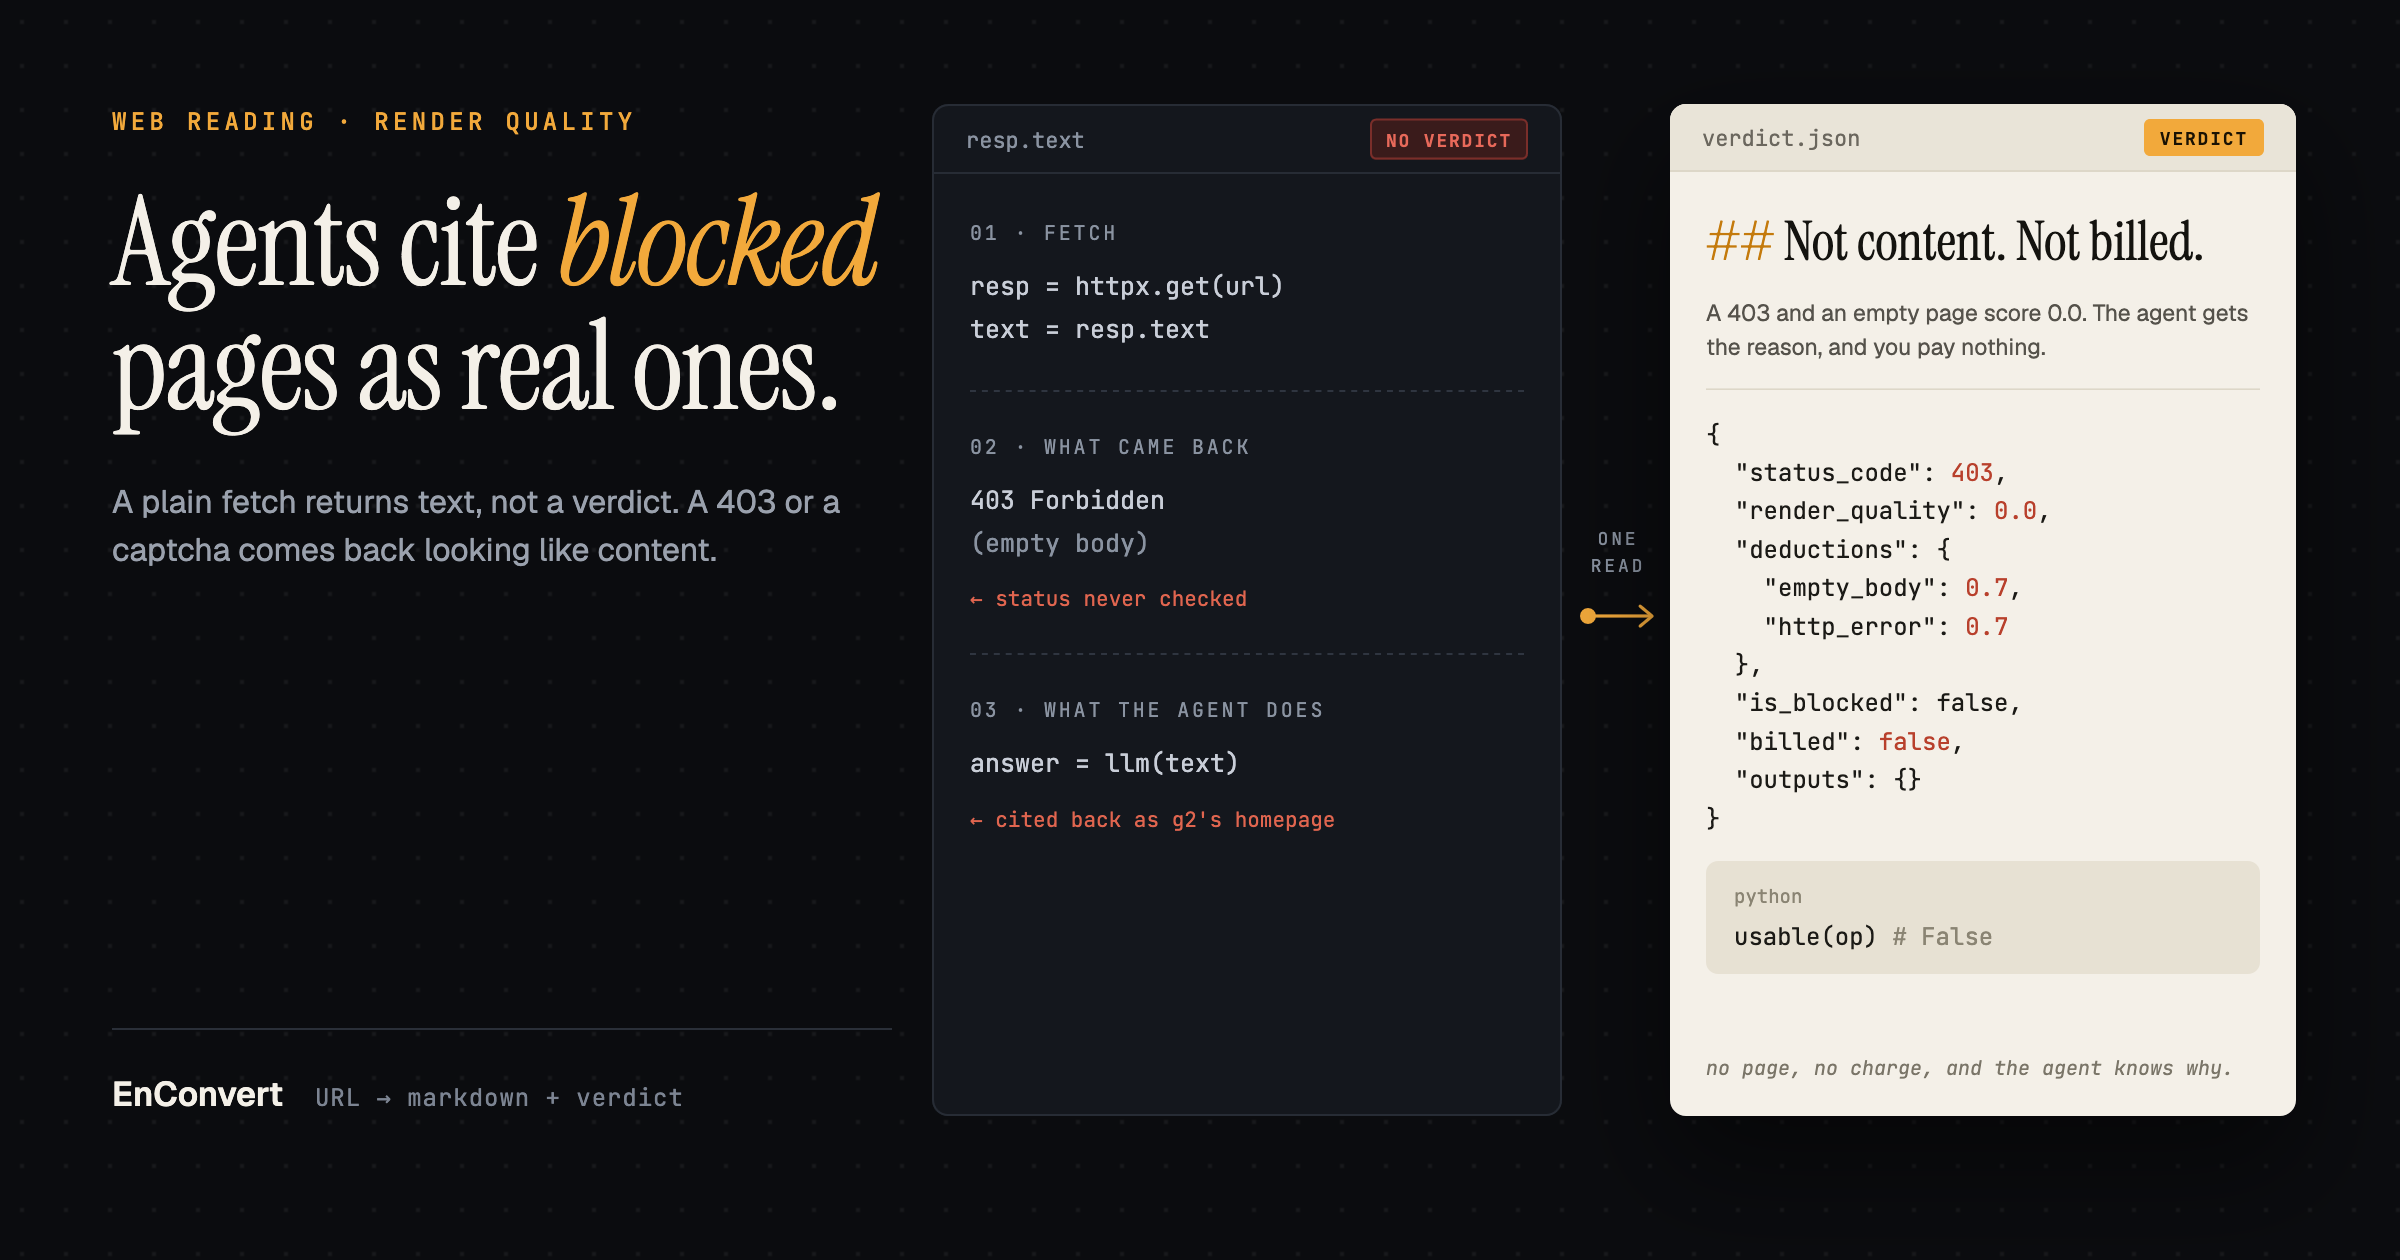
How render_quality works: 11 named deductions, a 0.40 floor, is_blocked, what the scorer still misses, and the MIT version you can run on any reader
Every web read should come back with the page and a verdict on whether it's the page you asked for. How /v2/perceive returns both, and what it bills.
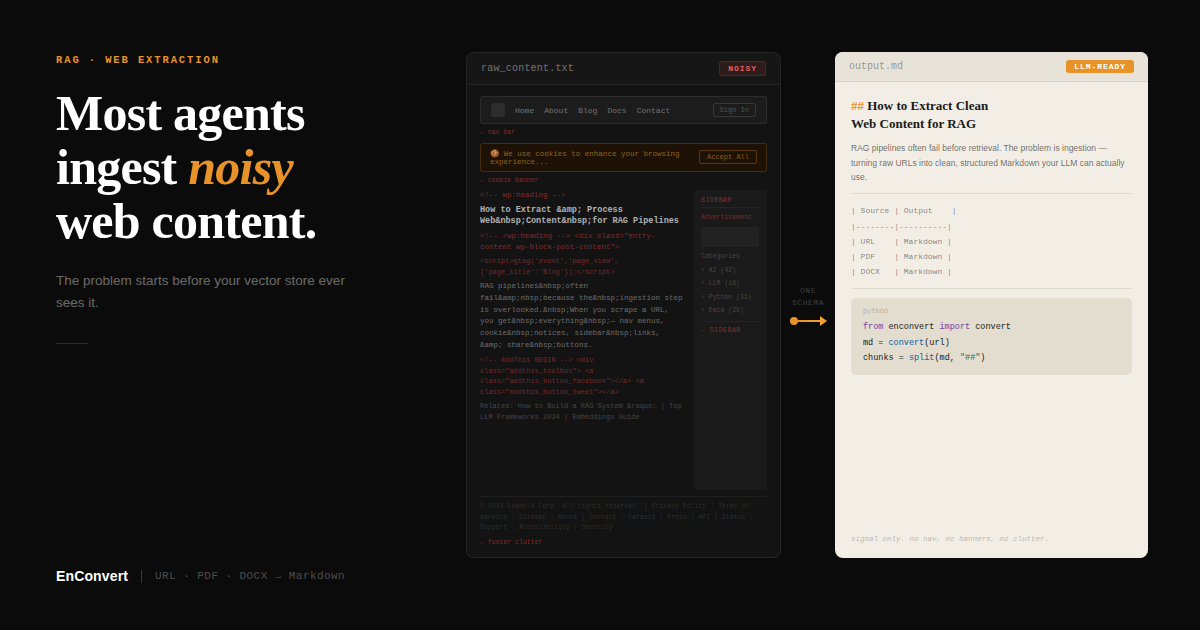
Most RAG pipelines break at web content extraction, not retrieval. This guide covers what raw extraction returns, what clean Markdown looks like, and what it ta...
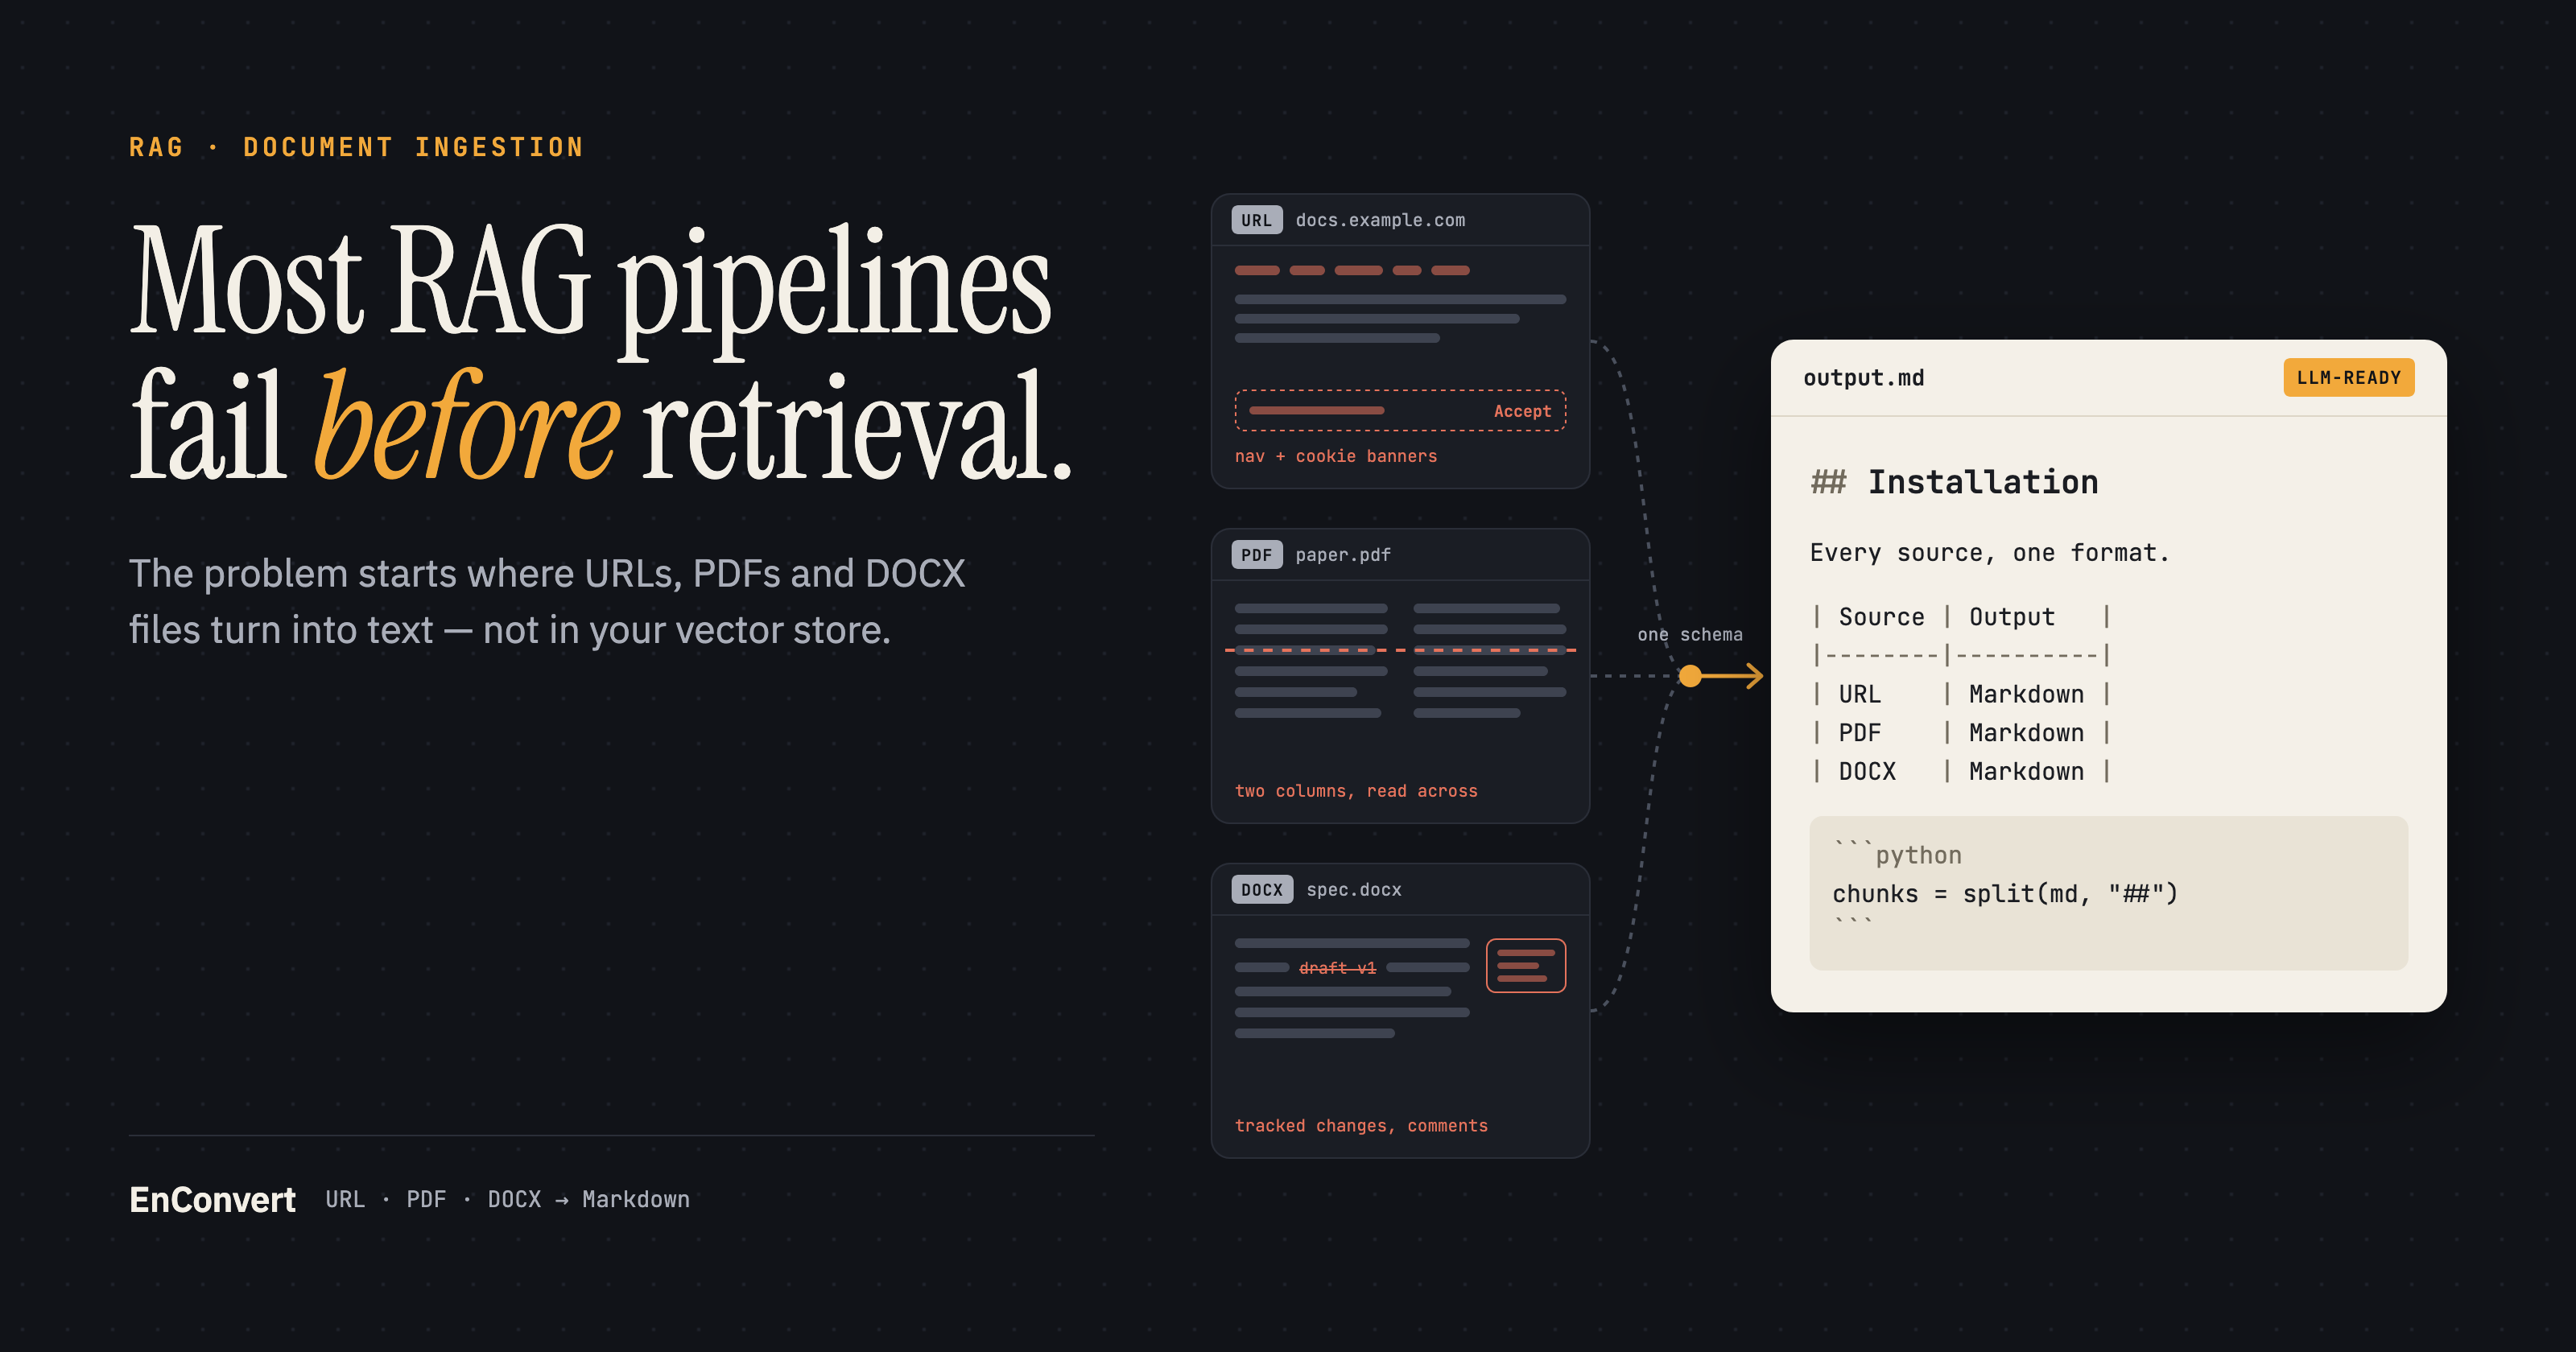
Most RAG pipelines break at ingestion, not retrieval. This guide covers what building a unified ingestion layer actually requires, what it costs to maintain, an...